Consumer AI
Nufeed
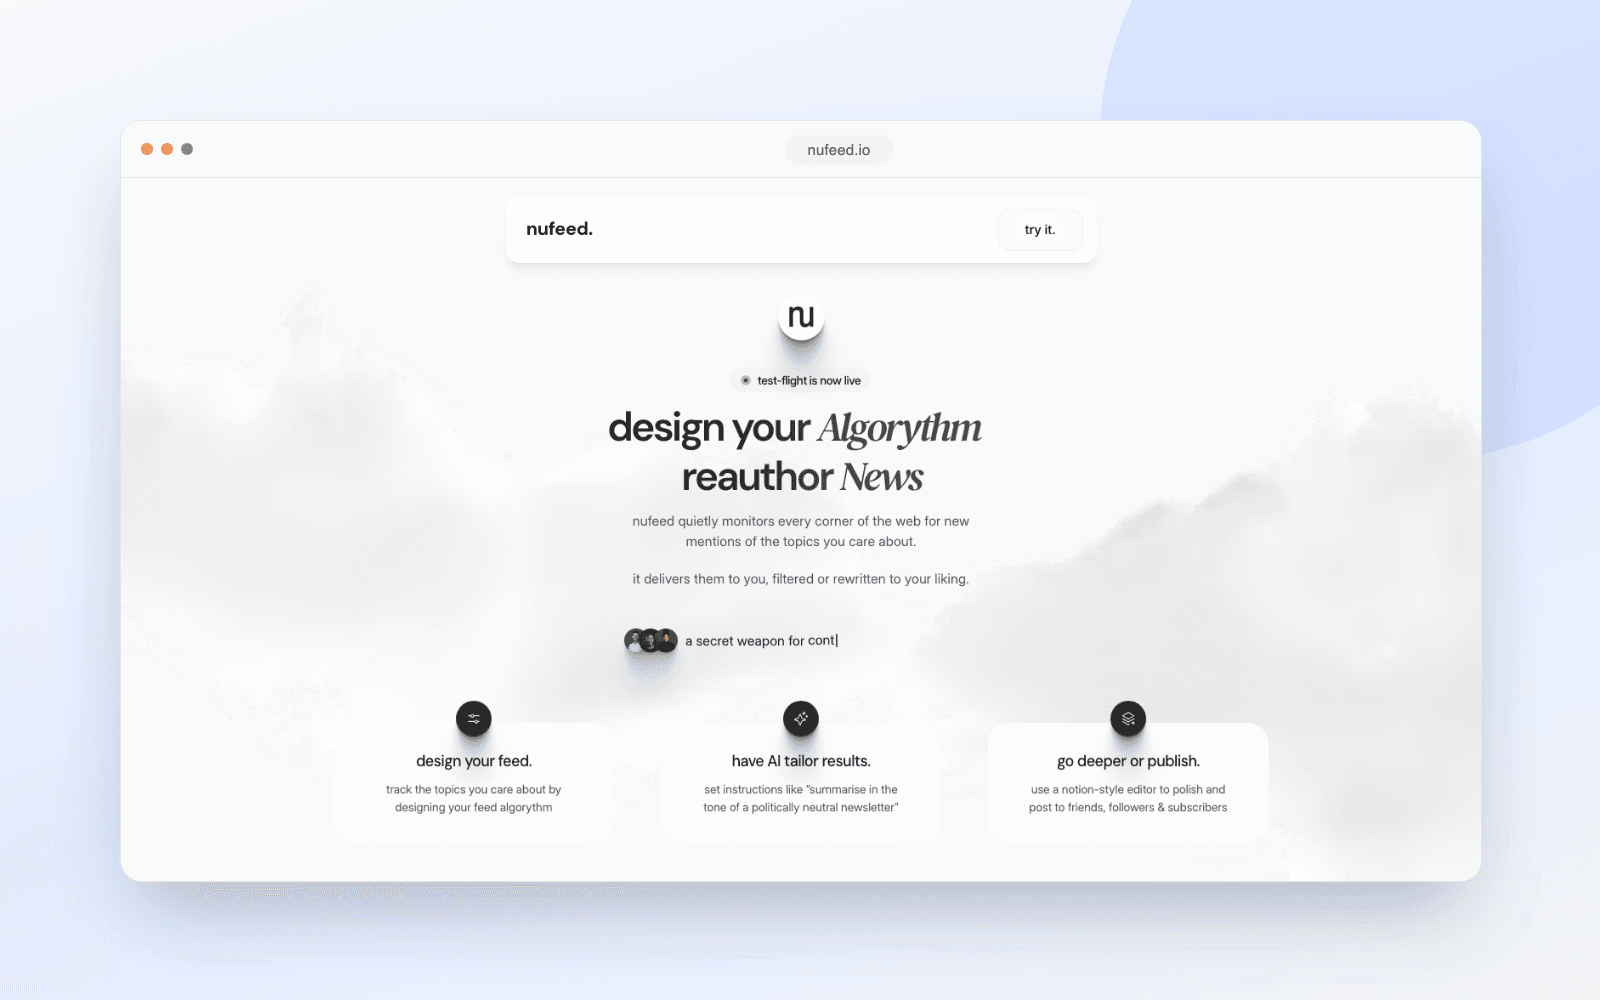
A personalised news feed that lets people design their own algorithm instead of inheriting one — taken from spec to a public test-flight in weeks.
<2s
per-topic feed rewrite latency
- Next.js
- LLM pipelines
- Content
Making a system behave predictably under conditions you have not seen yet. Load modelled from real traffic shapes, failure modes worked through deliberately, and instrumentation that tells you something before a customer does. Usually run by an engineer already deployed on the build, because the person who knows where it is thin is the person who wrote it.
If more than one of these is true, this is usually the right starting point.
Three to five weeks of a deployed engineer, often alongside a build.
The sequence this work follows, and why it is in that order.
Traffic shapes taken from production, not a flat synthetic ramp. Real systems fail on spikes, uneven key distribution and retry storms — none of which a smooth load test reproduces.
Every dependency gets the same question: what happens when this is slow, and what happens when it is gone? Timeouts, retries and circuit breakers follow from the answers rather than from defaults.
An alert that does not name who responds and what they do is a notification. We delete those. What is left is a smaller catalogue that people actually trust at 3am.
Game days against the failure modes we found, with the runbooks in hand. The first time you execute a runbook should not be during an incident.
Chosen per deployment, not per fashion. If your team already runs something that works, we work in that instead.
Consumer AI
A personalised news feed that lets people design their own algorithm instead of inheriting one — taken from spec to a public test-flight in weeks.
per-topic feed rewrite latency
Most deployments draw on more than one of these.
Talk to an engineer who has done this before — and if this is the wrong place to start, they will say so.